Conversations
5 min read
Red Hat: twenty years of pahole, structs to BPF
Arnaldo Carvalho de Melo of Red Hat on how pahole became part of every kernel build, BTF for Rust, and perf profiling data structures.
By  Luca Berton
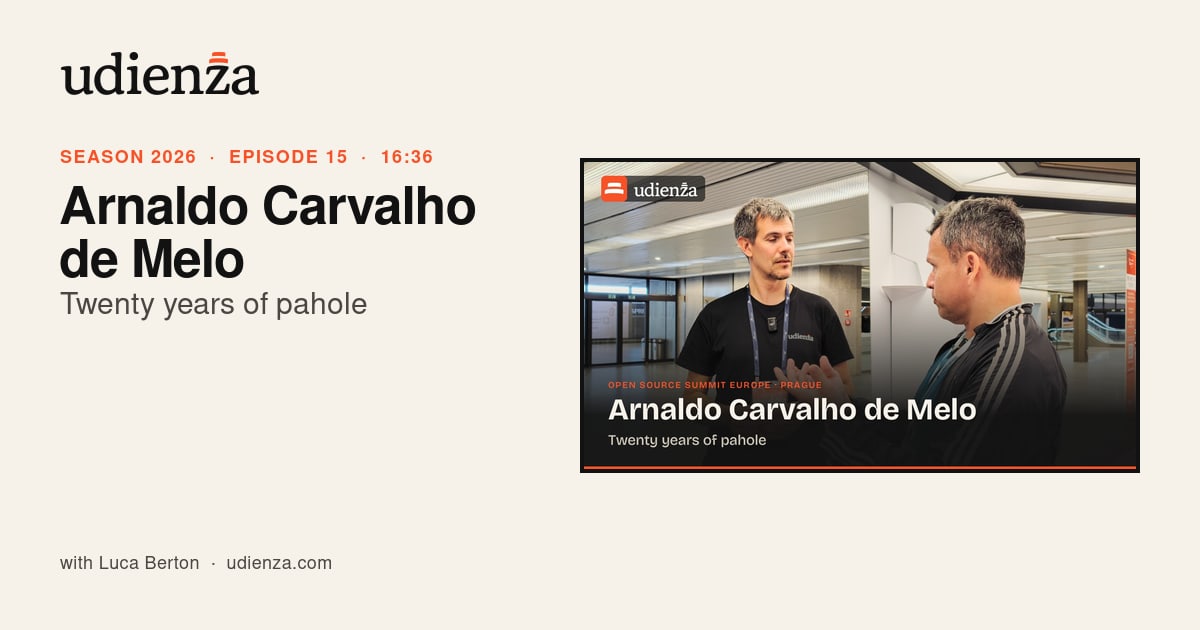
Arnaldo Carvalho de Melo works for Red Hat from Brazil, and maintains pahole and the user-space perf tooling of the Linux kernel. Luca Berton talked to Arnaldo at Open Source Summit Europe in Prague on 7 October 2026. The subject was twenty years of pahole, and how a tool for inspecting and packing data structures became something every kernel build depends on. Who else the show met that week is in Open Source Summit Europe 2026.
Twenty years from Brazil
Arnaldo has always worked from Brazil, for Red Hat for the last 20 years. Before Red Hat, Arnaldo had a company in Brazil that commercialized Linux and had a Linux distribution, and a lot of Linux developers came from it or got their start with Linux there. Arnaldo names some of the people of that time: Rik van Riel, who worked on memory management in the 2.4 to 2.5 kernel era, and Marcelo Tosatti, a Brazilian who maintained the kernel for a while.
At Red Hat the first job was networking: reorganising the structures behind the kernel’s network protocols, TCP/IP, v4 and v6. Arnaldo then joined the team that had Ingo Molnar, Thomas Gleixner, Peter Zijlstra and Steve Rostedt, productising real-time. Along the way Ingo asked whether Arnaldo would like to contribute to the user space for perf, which Arnaldo has maintained “since 2009 or something like that”.
How pahole met BPF
A lot of people identify Arnaldo with BPF, Luca said. The story starts in 2015, when Alexei and Daniel, the main BPF developers then, came to Arnaldo because Dave Miller had told them that pahole understood DWARF and also CTF, the compact type format used by DTrace on Solaris. BPF needed something similar. They looked at the pahole code base, saw a CTF loader and an encoder that produced CTF from DWARF, and designed BTF around that.
BTF is now used to allow lots of features, such as compile once, run everywhere. A BPF program may have been built for a previous kernel, and the layout of a data structure it uses may have changed since, so relocations have to be done. Because BTF is an integral part of BPF, “every kernel that’s built has to use pahole to convert DWARF to BTF, to enable the BPF ecosystem to work.”
Why not the compiler? Clang and GCC only generate BTF when they build BPF bytecode, not for x86-64, ARM or the other native targets. BPF evolves fast, and waiting for the compilers would slow it down, so an extra tool introduces the concepts first, and “eventually the compiler, which is the right place to do this kind of thing, will do it.”
Why 32 bytes matter
The original job has not gone away. pahole “started as a way for us to help in reducing memory usage and make more efficient use of the cache hierarchy”. Saving 10, 12 or 32 bytes sounds small, but “it’s 32 bytes per connection”, on a machine that can have thousands of connections. The first-level cache can be as small as 64 kilobytes, and using that scarce resource well is what lets a machine serve more connections and process packets faster.
BTF for Rust
The first piece of current work is extending BTF to support Rust. Rust is now used to build components inside the kernel, and people want the same tracing abilities for them that tools like bpftrace give for the components written in C. But Rust is more expressive, with concepts like traits and enums that have functions, and BTF was designed for C. So BTF has to be extended to enable tracing of Rust components.
Profiling data, not code
The second is a new feature in perf. “Instead of profiling code, you profile data structures.” perf samples stores and loads to find false sharing: the same cache line accessed in close succession by different CPUs, one writing and the other reading, so the cache is invalidated and has to be refreshed from memory. NUMA makes it worse, and so do chiplets that each share their own cache, “kind of like a mini-numa”. The fix is to move fields so that what is mostly read stays in the cache for longer.
The same sampling finds fields that belong together. Reading an integer brings in a whole cache line, usually 64 bytes, so what is in that line should be what the next instruction or function will use. By resolving sampled accesses to their type, such as struct tcp_sock, and looking at a sliding window of around 10 microseconds, the samples can show that a field should move to the other cache line, so that one cache line is brought in instead of two.
This matters most when moving large amounts of data, Arnaldo says, such as AI inference between machines like a DGX Spark with 200-gigabit ports, where it means more tokens per second. Luca described a benchmark of NFS over RDMA against traditional NFS version 4.1, and working with GPUs that access storage directly but need RDMA access. Every piece of hardware has its own characteristics and its own ways to count events, Arnaldo answered, so you need tools like perf to observe it and then act on the numbers. “In these extreme cases, every 1%, 2% counts”, because the machines are very expensive.
Keeping the gains
Luca asked whether observability is the next hot topic. “If you don’t look at what’s happening, you don’t know what’s happening.” A structure tuned with all these techniques can lose its performance when someone adds a field in the wrong place the next day: “it’s difficult to optimize something, it’s easy to pessimize.”
That is the case for continuous profiling in production: collecting all the time, and using inference to analyse the samples. The kind of data or the kind of requests can change, prompts can get bigger, and correlating those changes with the performance of a workload is difficult. Collecting all the time and running inference continuously can find things that improve the efficiency of the workload.
More
The conversation is on the episode page for Arnaldo Carvalho de Melo, and its second part on its own page.
Questions and answers
Why does every kernel build run pahole?
BTF is an integral part of BPF, and Clang and GCC only generate BTF when they build BPF bytecode. For every other target, pahole converts DWARF to BTF during the kernel build.
What does it mean for perf to profile data structures?
Instead of profiling code, perf samples loads and stores and resolves their types, to find false sharing and fields that are accessed together but sit on different cache lines.
Why profile continuously in production?
A change made the day before can add a field in the wrong place and cause a performance regression. Collecting samples all the time, and analysing them with inference, can find what is happening and what would improve the efficiency of the workload.
Built something the rest of us run on? Being a guest is free. Take the other chair
Related articles
All articles →-
Conversations · 5 min read
Linux Foundation: inside the stable kernel
Greg Kroah-Hartman on AI tools that find kernel bugs, why a phone runs more of Linux than a server, the CRA, students, and 35 years of maintaining.
-
Conversations · 3 min read
AgentCat: the silent failures of MCP servers
Kashish Hora of AgentCat on the silent failures that MCP servers' logs never show, a one-line SDK that lets agents report back, and the agent experience.
-
Conversations · 1 min read
OpenBao 2.7: post-quantum and HSM keys
Alex Scheel of Control Plane on OpenBao 2.7: horizontal scaling on PostgreSQL, PKI roots backed by an HSM, post-quantum support and the roadmap.
The episodes in this article
All episodes →-
Episode 15 · 3 Nov
Arnaldo Carvalho de Melo: Twenty years of pahole